FOLIO
May 2025Team project with Uzair Ahmed — roughly equal contribution
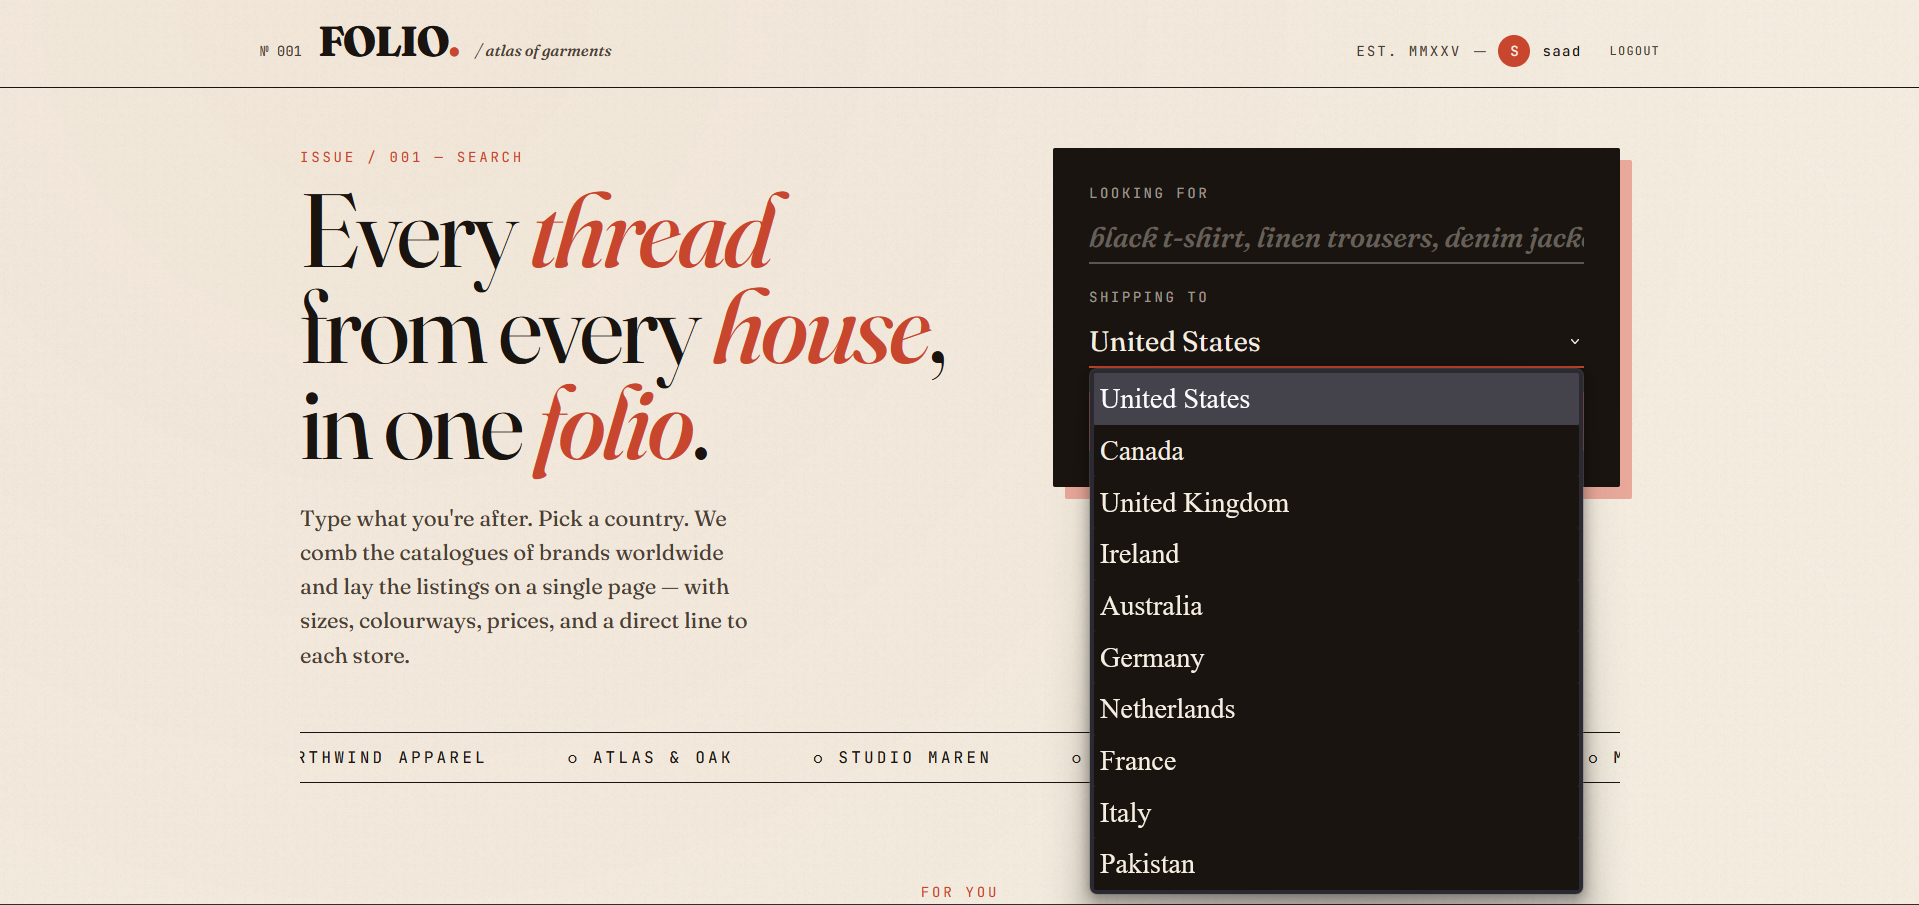
A distributed big data clothing search engine and recommendation pipeline that ingests public product catalogues across 10 countries (US, CA, GB, IE, AU, DE, NL, FR, IT, PK), streaming listings through Apache Kafka in KRaft mode and cleaning them in real time via Apache Spark 3.5.4 Structured Streaming. The system follows an ingest → stream-process → serve architecture, containerized end-to-end with Docker Compose, with a FastAPI backend serving a React 19 and Vite frontend.
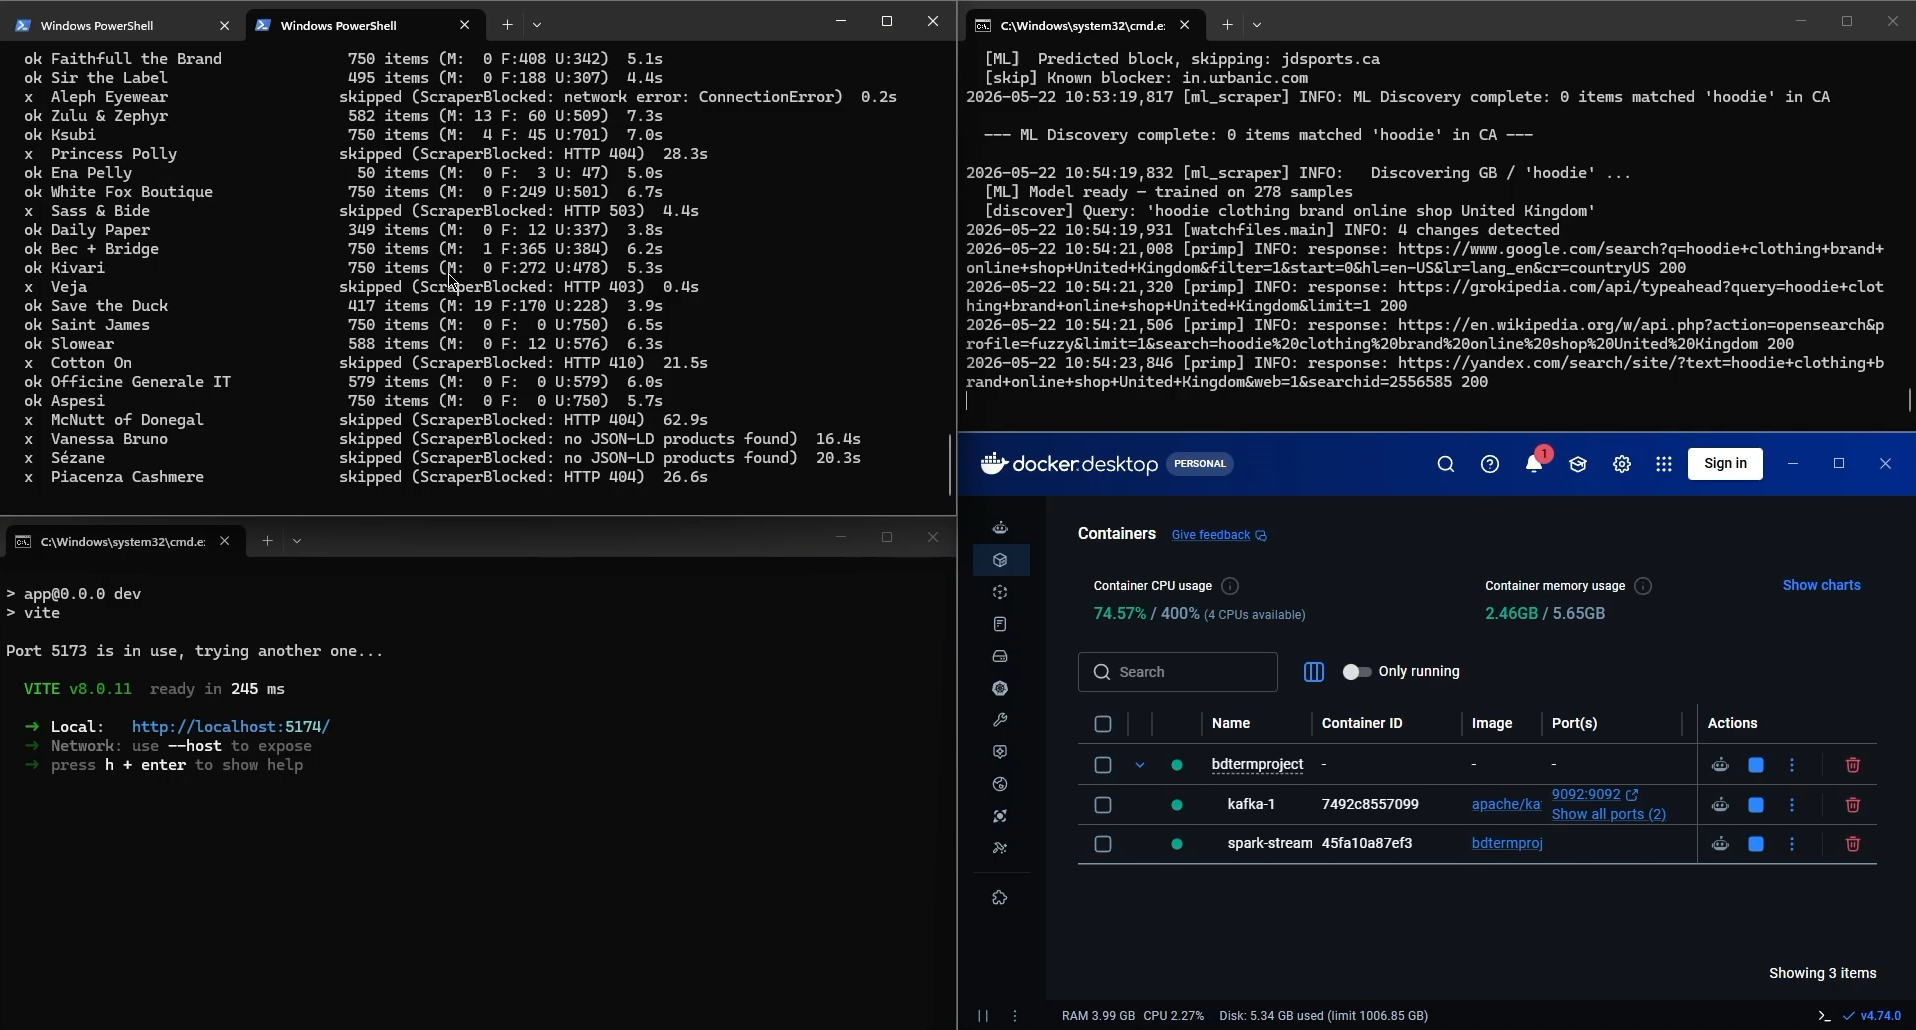
Python scrapers target Shopify endpoints and fallback JSON-LD structures across 40+ brands, publishing raw payloads directly to Kafka's `raw_listings` topic. Spark Structured Streaming consumes that stream to drop nulls, deduplicate items, filter invalid entries (price ≤ 0), normalize gender attributes into a fixed set, and prune extreme price outliers exceeding 10× the per-brand median — before writing clean records to an SQLite database with an FTS5 full-text search index.
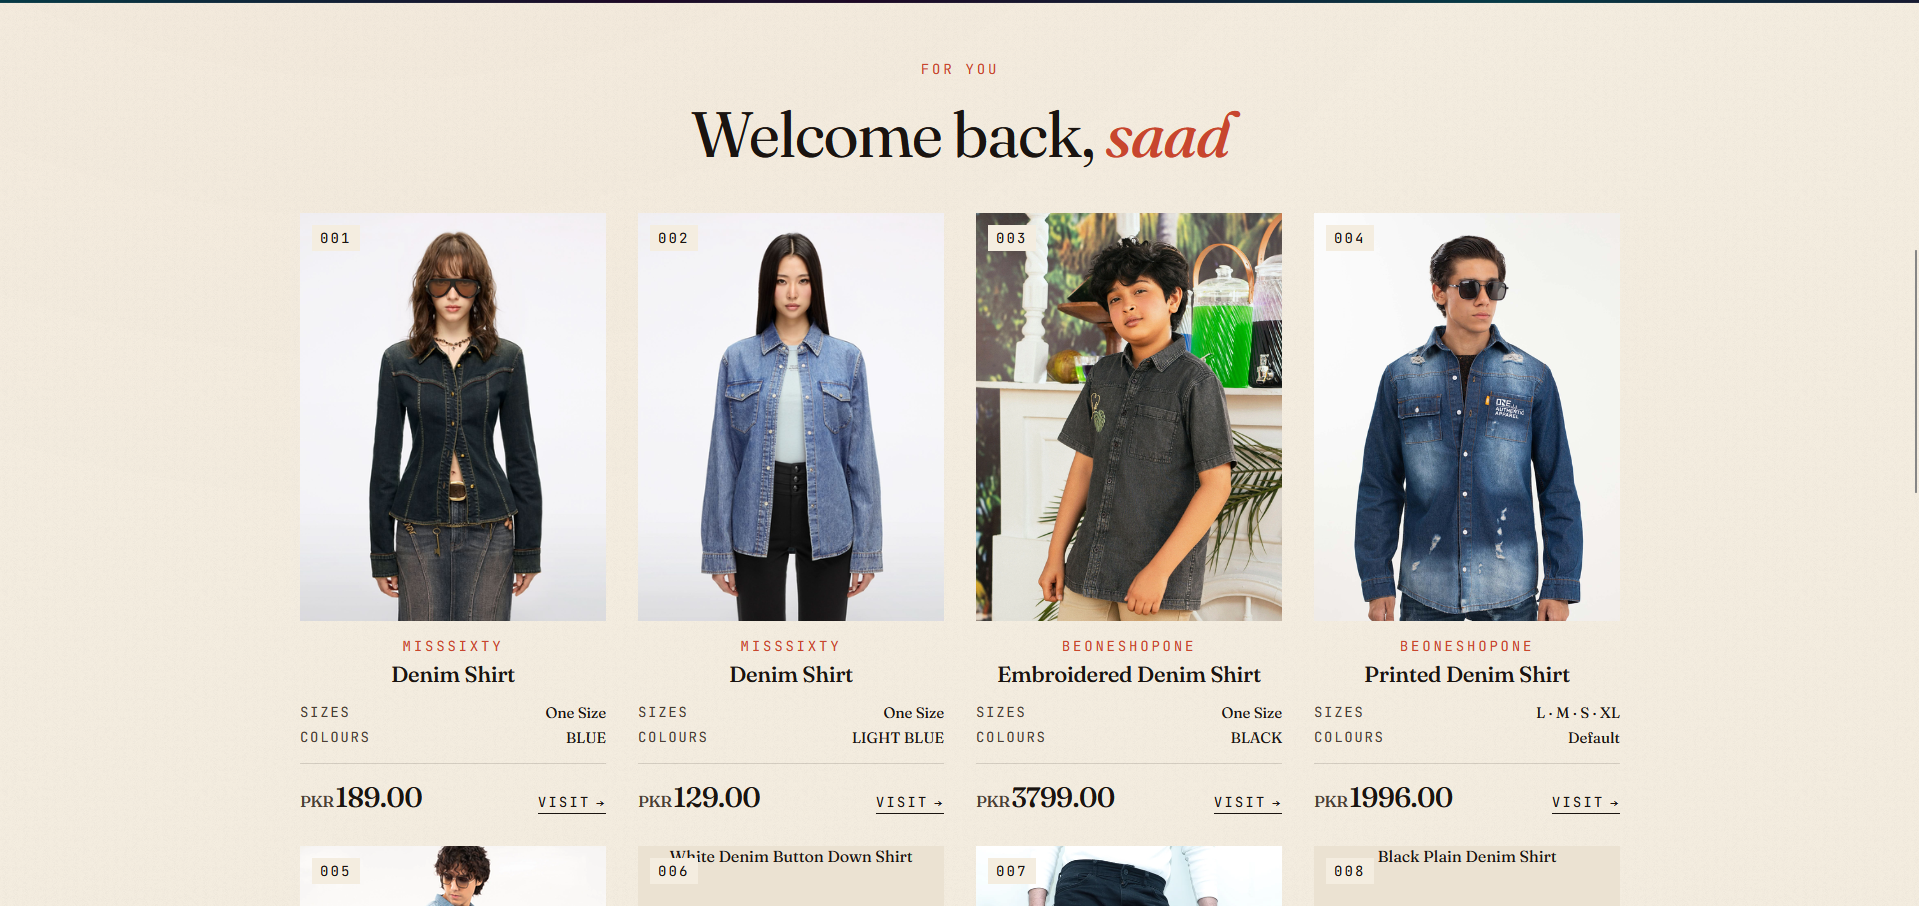
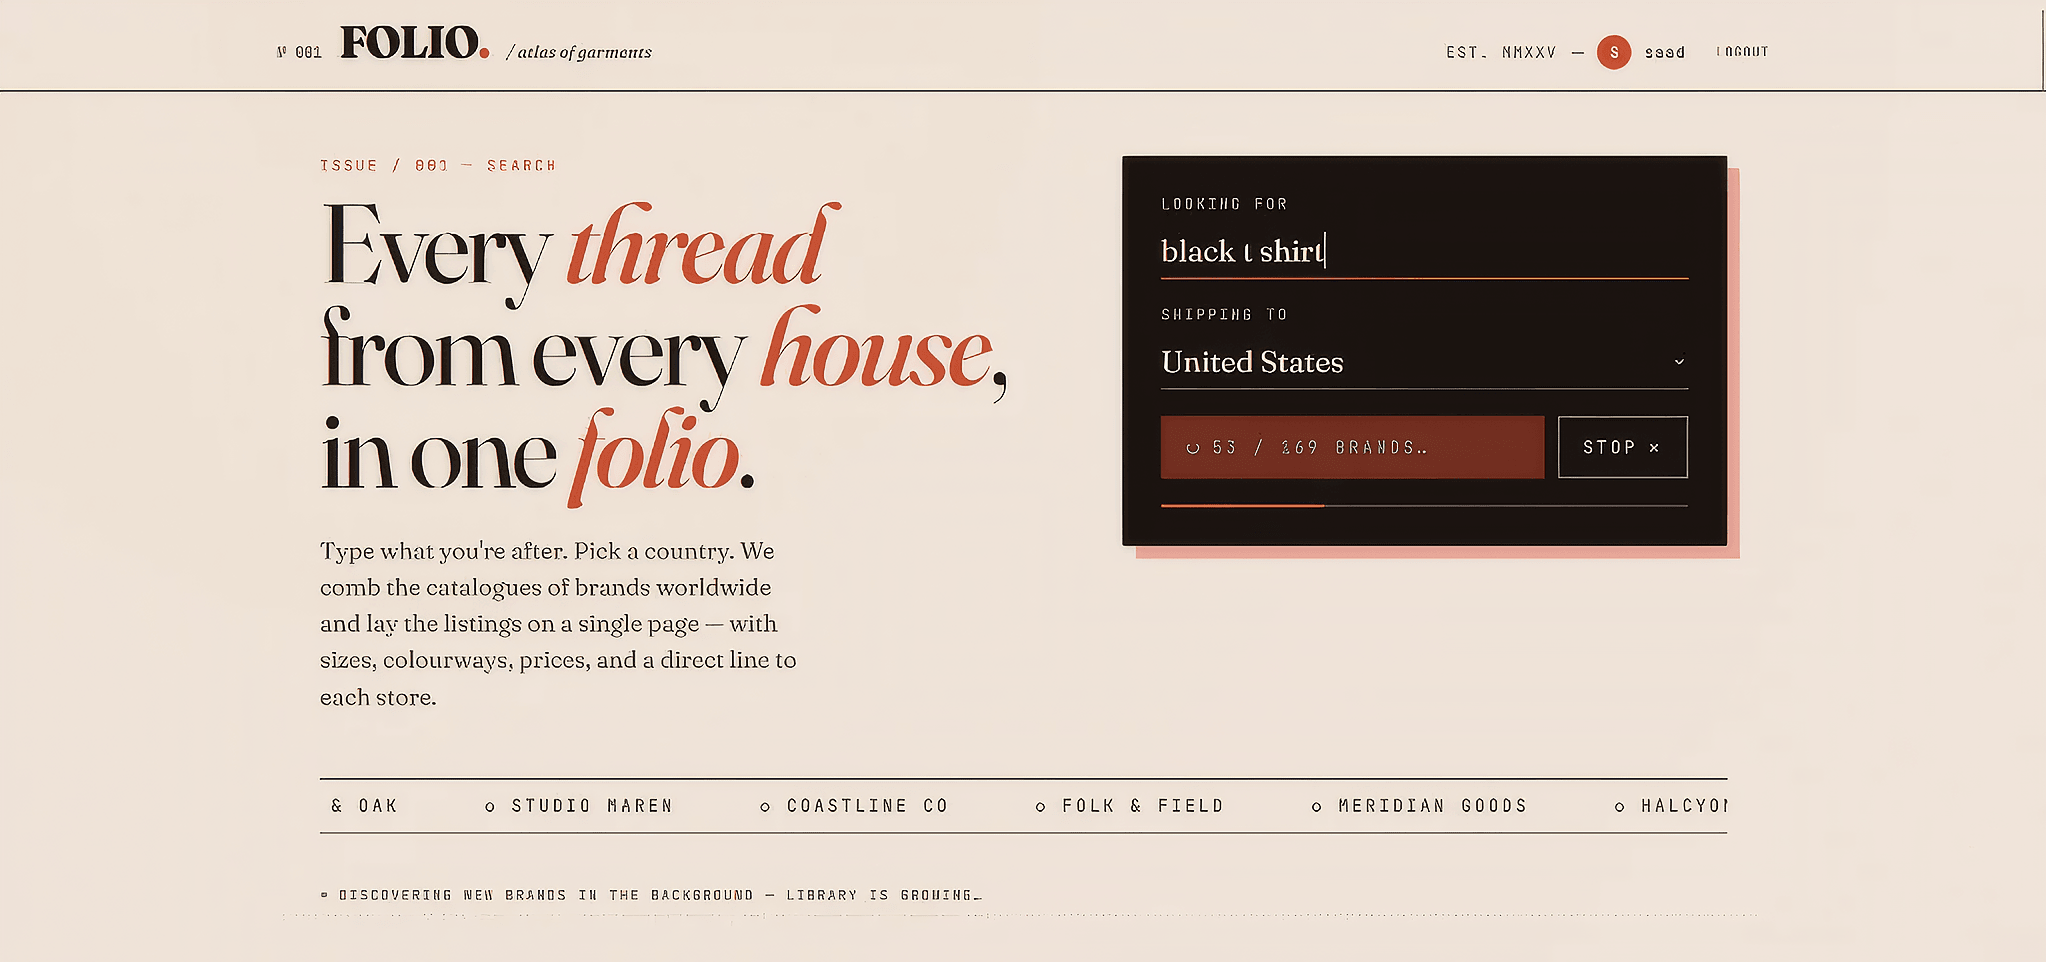
Search results are delivered in real time over Server-Sent Events via `/api/stream`, pushing immediate cached matches from SQLite while live scraping runs asynchronously in the background. Recommendations are computed over user search history using TF-IDF vectorization and cosine similarity, and a separate background machine learning thread pairs Google search discovery with a RandomForest classifier trained on tracking data to find and catalogue fashion brands not yet indexed by the system.
Built with
- Apache Kafka
- Apache Spark (PySpark)
- FastAPI
- SQLite (FTS5)
- React
- Vite
- Firebase Auth
- Firestore
- scikit-learn
- Docker Compose
- Python